Articles in this Volume

Research Article Open Access
Levels of Autonomy in Robot-Assisted Laparoscopic Surgery: Current Capabilities and Evolutionary Pathways
Article thumbnail
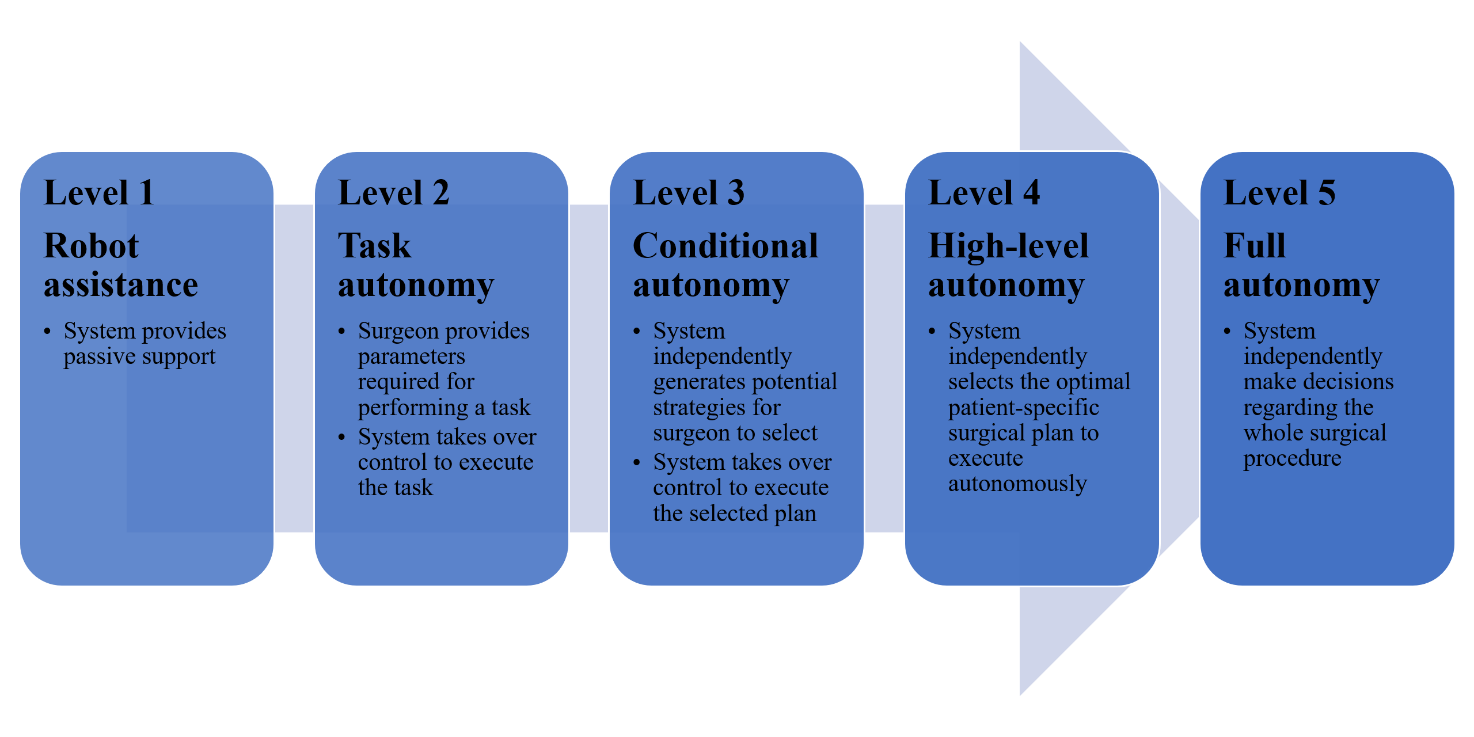
Robotic laparoscopic surgery is moving from conventional teleoperation toward greater autonomy. Previous studies usually only examined individual parts of this transition. The technologies enabling autonomous laparoscopic surgery are less often discussed as one integrated system. This review examines the system through three components: hardware infrastructure, environmental perception, and decision-making. The hardware discussion covers instrument actuation, vision and force sensing, and various robotic platforms. The perception section follows proprioceptive, visual and force data as they are converted into a unified representation of the surgical state. It focuses on 3D scene reconstruction, instrument segmentation, workflow recognition, and multimodal fusion. The decision and control section discusses classical control and data-driven methods, especially the hierarchical imitation learning and reinforcement learning for long-horizon surgical tasks. The review concludes with the main barriers to clinical translation, including the sim-to-real gap, deformable tissue modeling, and safety and regulatory requirements. These areas together show how embodied intelligence may influence future autonomous surgery in the operating room.
Show more
Read Article PDF
Cite
Research Article Open Access
Visual Explanation Methods for CNNs: Grad-CAM, Score-CAM and LIME
Convolutional Neural Networks (CNN) are not widely used in high-risk decision-making because they have black-box nature. This paper investigates three visualization methods, Gradient-weighted class activation mapping (Grad-CAM), Score-weighted visual explanations for convolutional neural networks (Score-CAM), and Local interpretable model-agnostic explanations (LIME), across classification, detection, and medical imaging tasks. Theoretically, Grad-CAM relies on gradient backpropagation to weight feature maps. This offers computational efficiency but suffers from gradient instability and coarse spatial resolution. Score-CAM replaces gradients with forward pass confidence scores. This enhances robustness and spatial alignment at the cost of linearly increasing inference overhead. LIME is a model agnostic surrogate. It provides flexible local explanations but is inherently sensitive to perturbation sampling and hyperparameter choices, leading to poor reproducibility. Grad-CAM performs best in dermatologist agreement and localization accuracy. Score-CAM show superior spatial alignment in pneumonia detection with gradient free robustness. LIME shows flexibility but suffers from instability and hyperparameter sensitivity. The differences are obvious: Grad-CAM is good at interpretability, Score-CAM is good at robustness with computational cost, and LIME is good at model agnostic applicability. Based on these differences, these three visualization tools can be selected for real-world tasks.
Show more
Read Article PDF
Cite
Research Article Open Access
A Case Study on the Robustness of Traffic Signal Control from a Data Science Perspective: The RobustLight Diffusion Reinforcement Learning Framework
Damaged sensor data, often caused by noise interference and data loss, impairs the decision-making accuracy of Deep Reinforcement Learning (DRL) traffic signal control models. This paper takes RobustLight (ICML 2025) as the core case and analyzes it from a data science perspective. We introduce DRL-based traffic signal control and diffusion model principles, then examine RobustLight's dual-process framework, DSI algorithm, Denoise and Repaint modules, and its non-Markov loss design. Experiments on Jinan, Hangzhou and New York datasets under four adversarial attacks and sensor damage show that RobustLight achieves up to 50.43% improvement in state recovery, with ATT reduced by up to 42%. Finally, we discuss real-world challenges including anomaly-detection dependency, inference latency, and cross-domain generalization.
Show more
Read Article PDF
Cite
Research Article Open Access
Vessel Trajectory Deviation Detection Using a Temporal-Attention LSTM Autoencoder
Article thumbnail
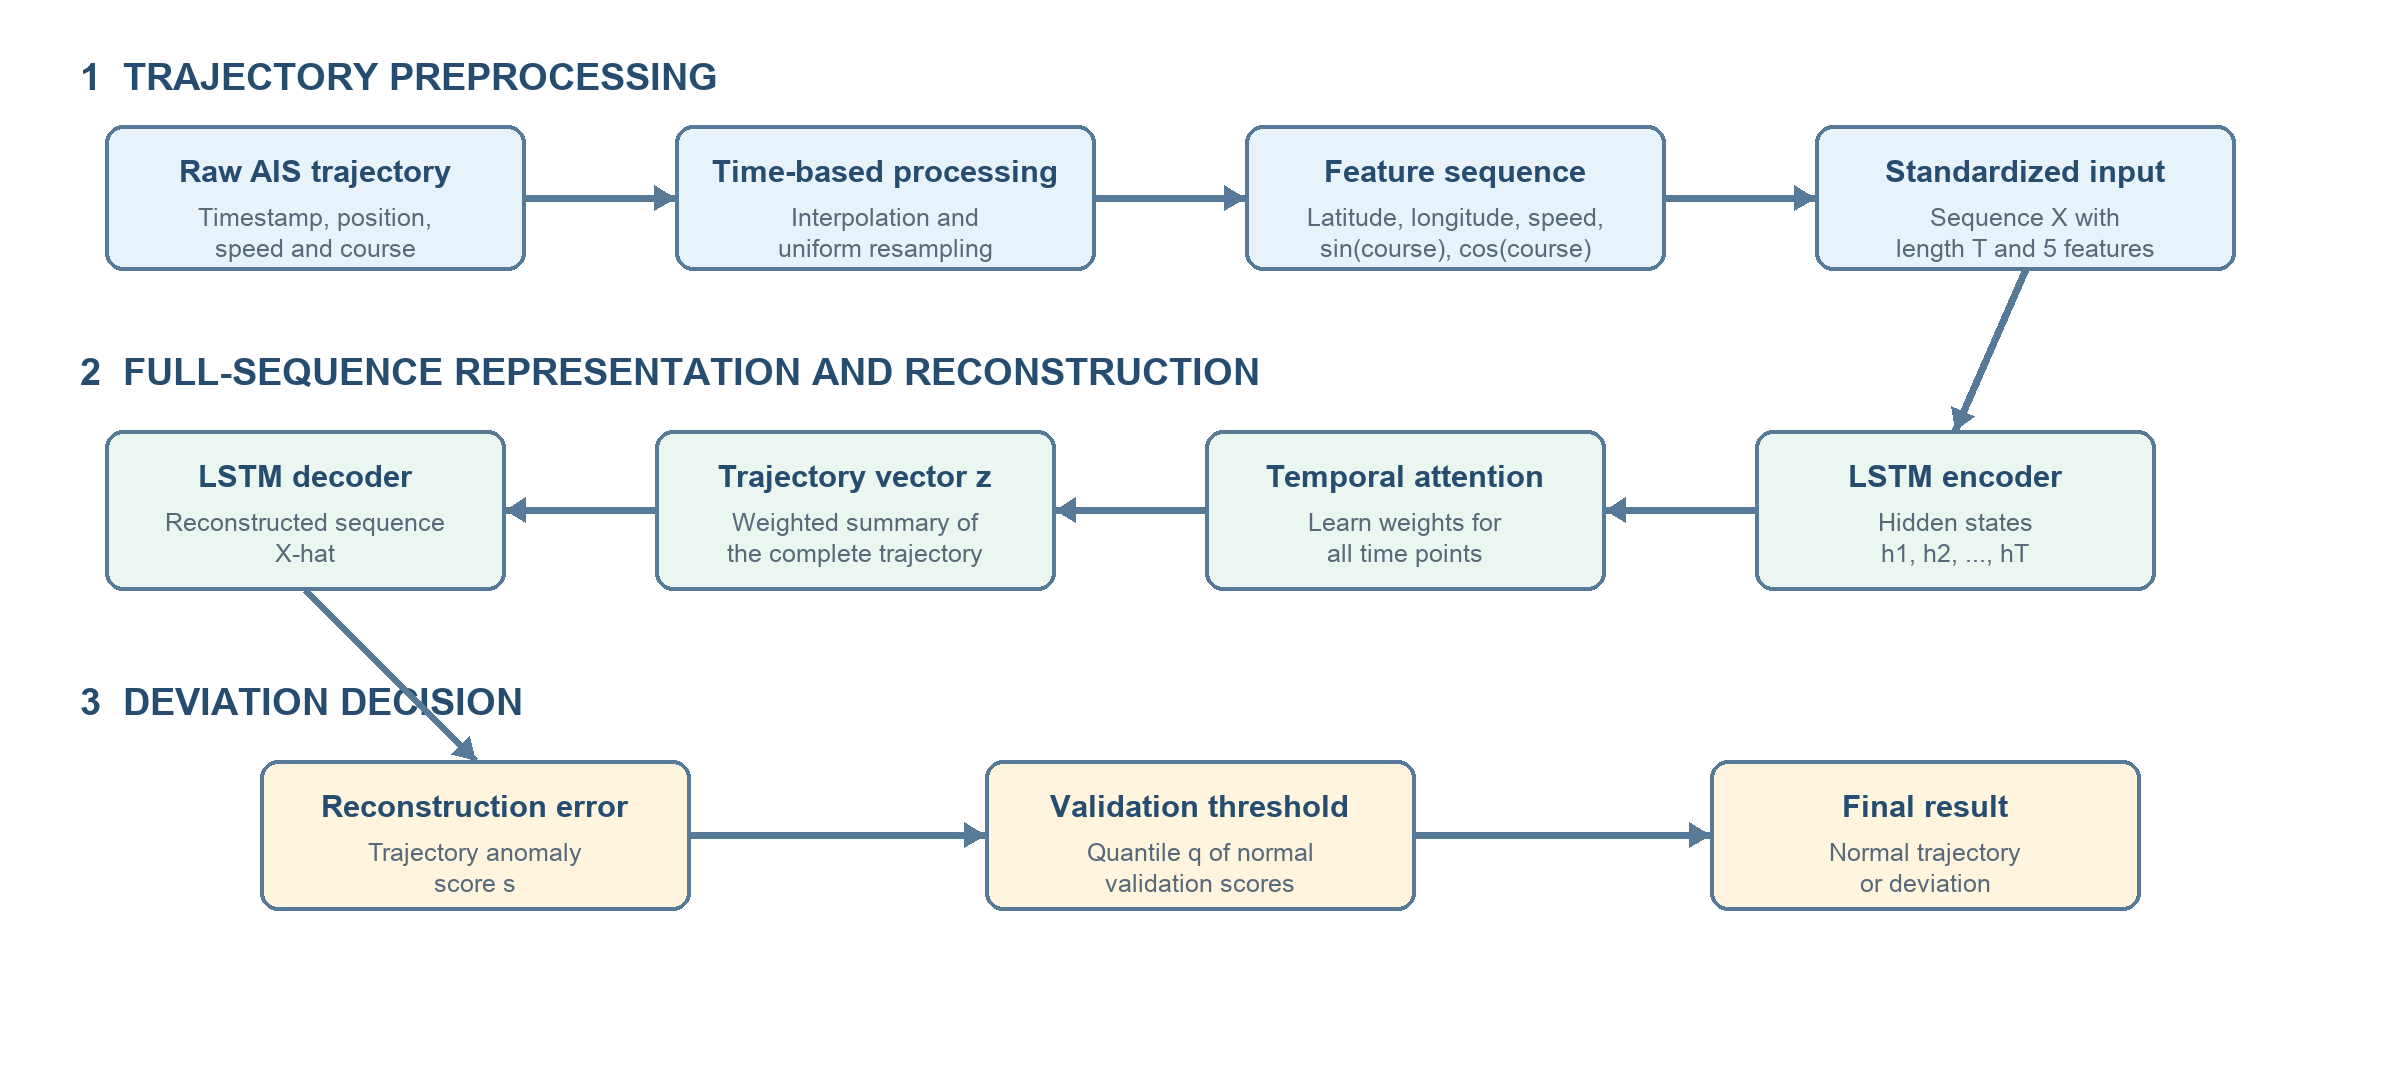
Abnormal vessel trajectories are critical indicators of potential collision risks, illegal navigation behaviors, and unexpected route deviations. This study uses labelled Automatic Identification System (AIS) trajectories from Danish waters to examine a Long Short-Term Memory (LSTM) autoencoder with temporal attention for vessel trajectory deviation detection. Latitude, longitude, speed, and course are processed as fixed-length sequences, and the model is trained only with normal trajectories. Reconstruction error is then used as the anomaly score. The model is compared with Isolation Forest, a dense autoencoder, a basic LSTM autoencoder, and a position-only LSTM model under the same Maritime Mobile Service Identity (MMSI)-based data split. Multi-seed repeated experiments over five independent runs show that the attention LSTM obtains a mean receiver operating characteristic area under the curve (ROC-AUC) of 0.859, recall of 0.725, and F1-score of 0.724. The improvement over the basic LSTM is small, while the dense autoencoder gives a slightly higher average precision. The results also show that speed and course are important for detecting abnormal movement. A sequence length and hidden size of 32, together with the 95th-percentile threshold, give the most balanced results. The dataset contains few abnormal samples, so further testing on larger datasets and different sea areas is still needed.
Show more
Read Article PDF
Cite
Research Article Open Access
Provenance-Aware Physics-Guided Feasibility-Region Learning for Pre-layout Two-Stage CMOS Op-Amp Sizing: A Calibration-Ready Workflow
Article thumbnail
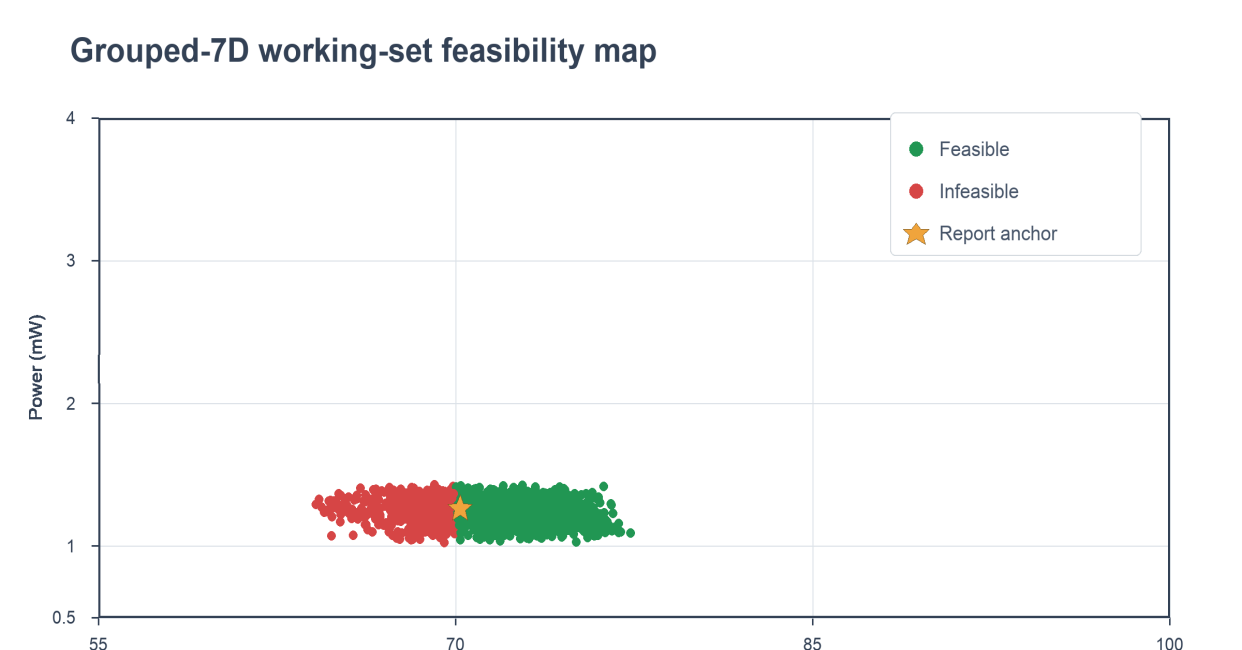
Analog operational-amplifier sizing is a costly multi-objective search problem: transistor dimensions and bias conditions jointly determine gain, bandwidth, stability, slew rate, rejection ratios, common-mode range, power, and offset. This paper presents a provenance-aware, physics-guided feasibility-region learning workflow for a two-stage CMOS operational amplifier. The report-anchored working set contains one TT baseline and 1,399 grouped-7D schematic-level rows. An independent LTspice 17.2.4 experiment contributes 96 portable schematic-level rows, including 32 complete cases, of which 20 satisfy the portable feasibility criteria. Six algorithmic entries are evaluated on the complete cases: Direct Ridge, physics-augmented Ridge, direct ExtraTrees, physics-augmented ExtraTrees, multilayer perceptron (MLP), and a constrained GP-UCB-style acquisition reference. The portable audit reports a mean normalized mean absolute error (MAE) of 0.393 for the policy reference, while MLP obtains the highest feasibility area under the precision-recall curve (AUC-PR) of 0.980. A one-round offline active-sampling replay ranks 5,000 grouped-7D candidates and selects 20 points; the macro normalized MAE remains 0.0664 before and after both the active and equal-size random additions. The report anchor is TT/pre-layout, and the working-set and portable-audit results are interpreted within their declared provenance rather than as process-general performance claims.
Show more
Read Article PDF
Cite
Research Article Open Access
Deep Learning-Based Visual Detection Technology for Metal Gear Surface Defects
Due to complex background interference, a lack of real defect samples, and inconsistent evaluation of real-time deployment in metal gear surface defect detection, four representative studies were selected for comparison and four technical approaches were analyzed: lightweight detection, interference resistance, few-sample augmentation, and production-line application. The results show that lightweight networks can increase the speed of detection; attention mechanisms and multi-scale feature fusion help suppress interference from oil contamination, shadows, etc.; and generative models can address the shortage of defect samples. Insufficient coverage of real samples still affects the model's generalization. Although the actual production-line system meets the cycle-time requirements, its false-positive rate and stability in the face of changes have not yet been optimized. Based on the above analysis, this paper proposes expanding the collection of real samples across different gear models and production batches, strengthening tests under complex imaging conditions, standardizing the evaluation of complete inspection time, and conducting comprehensive assessment using both false-positive and false-negative rates. The above recommendations provide a reference for the engineering application of visual inspection systems for metal gear surface defects.
Show more
Read Article PDF
Cite
Research Article Open Access
Parameter-Efficient Fine-Tuning of BERT: A Study of Fixed-Rank and Layer-Wise LoRA on SST-2
Parameter-efficient fine-tuning (PEFT) has emerged as a crucial method for adapting pretrained Transformer models to downstream tasks without the need to fine-tune the full set of model parameters. Low-Rank Adaptation (LoRA) is a technique that reduces the number of trainable parameters by representing weight updates with low-rank matrices. This paper explores the impact of LoRA rank selection and layer-wise rank allocation on the trade-off between classification accuracy and the number of parameters to be fine-tuned through fine-tuning BERT-base-uncased on the sentiment classification task, SST-2. The three fixed-rank LoRA settings with ranks of 4, 8, and 16 are first investigated, as well as a manually-designed layer-wise LoRA setting that assigns different ranks to different subsets of BERT layers. In the fixed-rank experiments, increasing the rank is beneficial to the validation accuracy, but the magnitude of the improvement seems to diminish with the number of trainable parameters. The layer-wise setup is able to attain 92.20% validation accuracy with 345,602 trainable parameters. It decreases the number of trainable parameters by approximately 41.6% and improves the validation accuracy by 0.57 percentage point, compared with LoRA at r = 16. It also can achieves performance close to full fine-tuning with 109,483,778 trainable parameters and 92.32% accuracy. The results indicate that with a non-uniform rank allocation it is possible to achieve an effective compromise between the efficiency of the parameters and the goodness of the downstream classification.
Show more
Read Article PDF
Cite
Research Article Open Access
Evaluation Framework for Emotional Experience in Visual Art Based on Psychometric Feedback
Article thumbnail
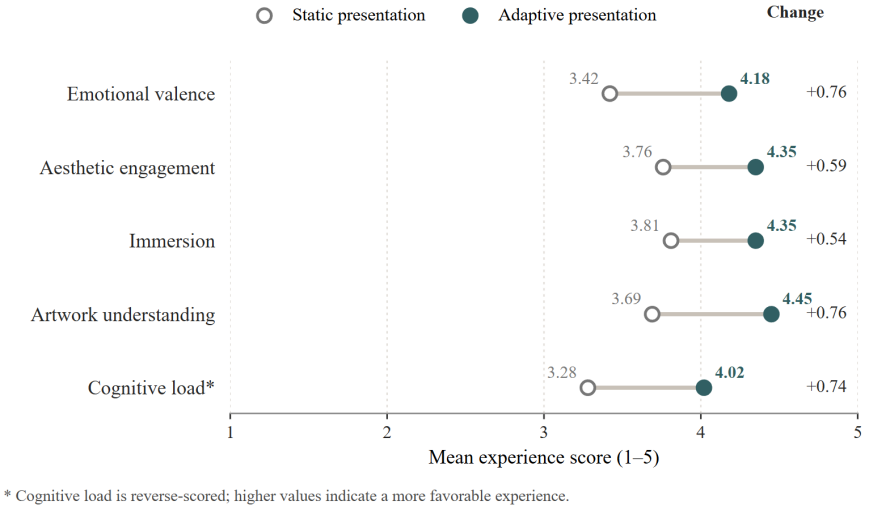
With the development of digital art exhibitions, intelligent display platforms, and interactive art systems, visual art experiences have gradually shifted from static viewing toward dynamic interaction based on user-state feedback. However, conventional art evaluation methods mainly rely on subjective questionnaires after viewing, which makes it difficult to capture emotional changes during the viewing process and support real-time visual optimization. To address this issue, an adaptive intervention evaluation framework for emotional experiences in visual art based on psychometric feedback is proposed. The framework integrates psychometric data, viewing behavior features, and facial behavior information to construct an emotional-state recognition model. Based on recognition results, visual factors including color, visual complexity, motion rhythm, and narrative prompts are dynamically adjusted. Sixty participants were recruited for experiments comparing static presentation and adaptive presentation conditions. The results show that the multimodal random forest model achieved superior emotional-state recognition performance, with an 85.00% accuracy in cognitive-load classification and a Macro-F1 score of 0.843. The adaptive presentation condition improved emotional valence, aesthetic engagement, immersion, and artwork understanding. This study provides a computational approach for emotional computing and personalized experience optimization in digital art environments, promoting the integration of artificial intelligence and visual art evaluation.
Show more
Read Article PDF
Cite
Research Article Open Access
Communication-Efficient Federated Learning under Non-IID Data: Aggregation and Compression Strategies
Article thumbnail
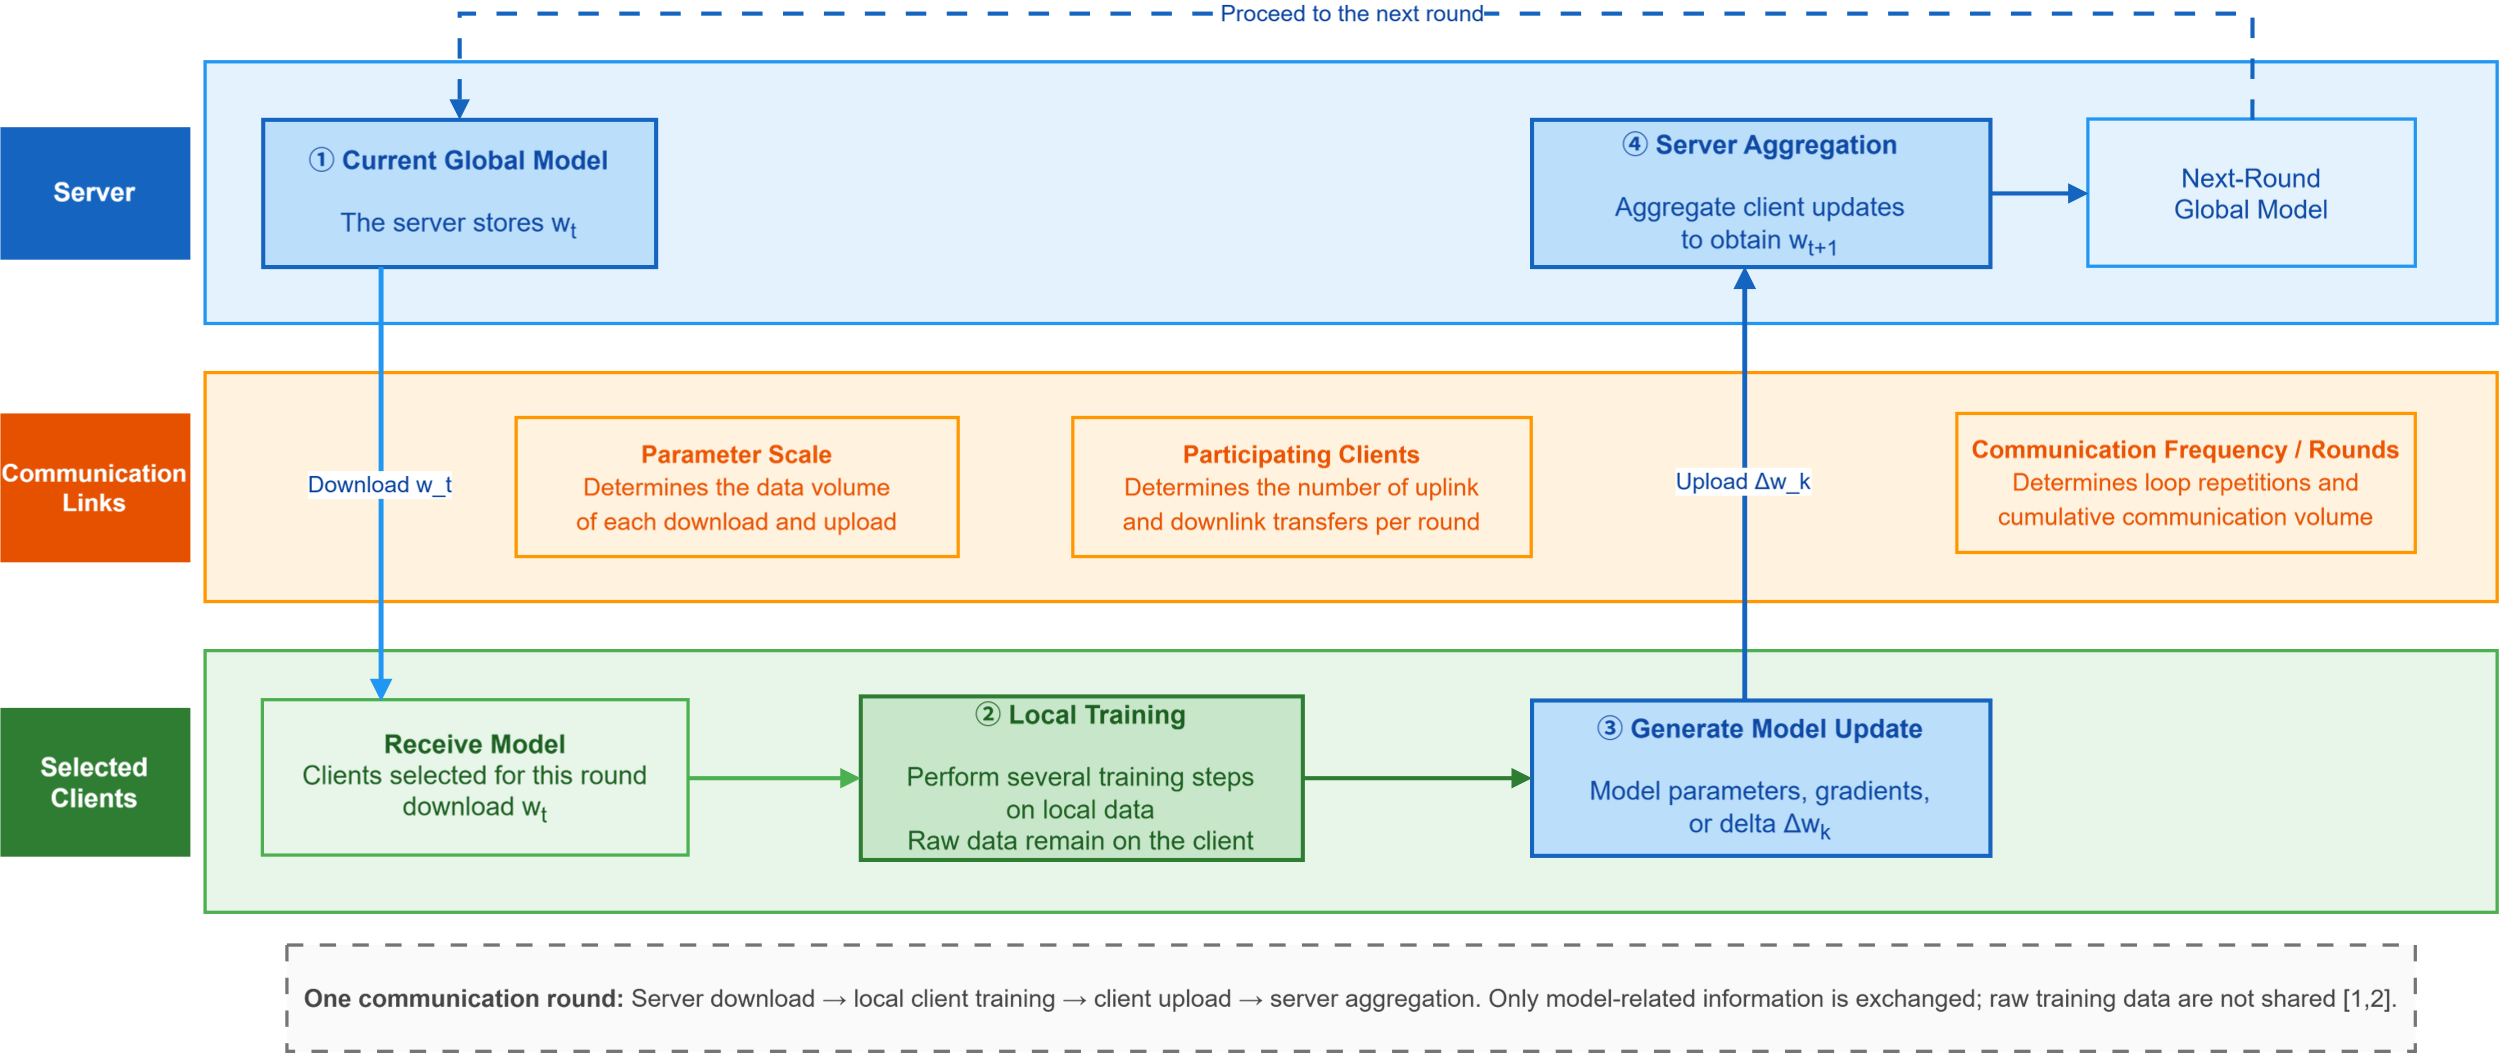
As data in scenarios such as medical, transportation and the Internet of Things continue to be dispersed to institutions and edge devices, how to balance the quality of model training and communication costs without concentrating raw data has become an important issue in the deployment of federated learning. Federated learning faces a coupling bottleneck between client drift and communication overhead under non-independent and non-identically distributed (Non-IID) data. This paper reviews aggregation, compression and hybrid strategies with representative studies, and verifies Federated Averaging (FedAvg), Federated Proximal (FedProx) and their error-feedback Top-k combinations (FedAvg+EF-Top-k and FedProx+EF-Top-k) under the unified setting of Fashion-MNIST. The results show that compression can significantly reduce the cumulative uplink communication required to reach the target accuracy and enable more training rounds under a fixed total communication budget. However, strong heterogeneity is associated with greater run-to-run variability, and communication rounds, transmitted bits, and end-to-end time cannot be substituted for one another. Based on literature comparison and verification results, this paper proposes a selection strategy according to data heterogeneity, bandwidth and system constraints, and recommends the unified reporting of accuracy, communication volume, communication rounds, time, and energy consumption.
Show more
Read Article PDF
Cite
Research Article Open Access
Performance E valuation of E xploration S trategies on L earning E fficiency and S tability in Q-Learning
Article thumbnail
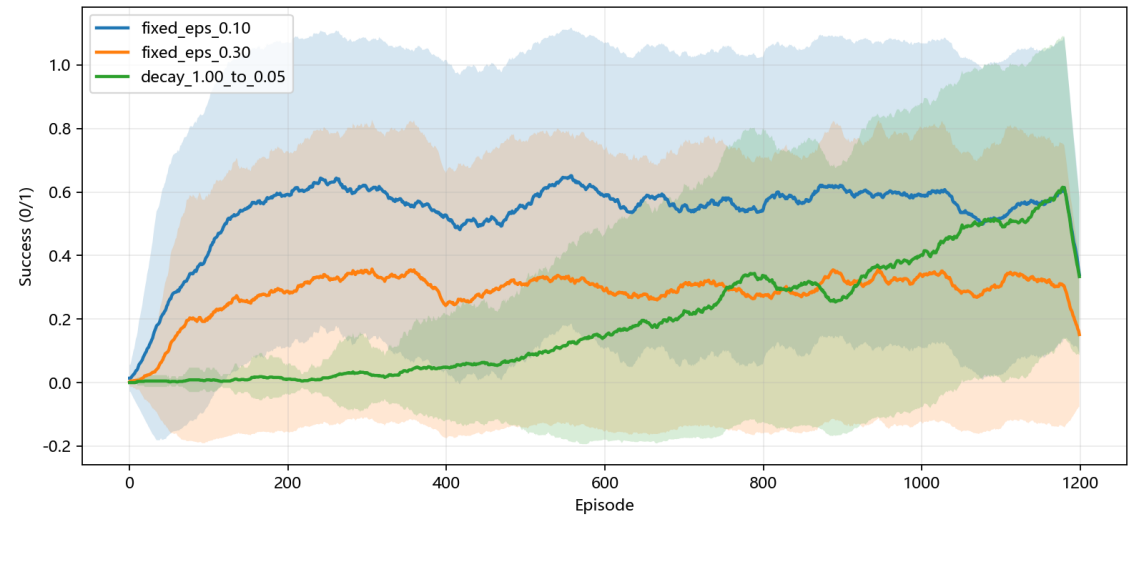
A fundamental problem in reinforcement learning is the trade-off between exploration and exploitation. The quality of the final policy is not the only factor that varies with different exploration strategies, so do learning speed and result stability. Based on Q-learning, this study compares three exploration strategies in a custom 5×5 GridWorld environment: fixed ε=0.10, fixed ε=0.30, and linearly decaying ε (1.00→0.05). A baseline experiment is first performed with slip_prob=0.10. The environmental noise is then extended to three levels, 0.00, 0.10, and 0.20, and the number of episodes required for the rolling 50-episode success rate to first reach 50% is used to measure learning speed. The results show that the fixed lower exploration rate learns faster overall under all three noise levels and demonstrates better stability across random seeds. Decaying exploration achieves a higher final success rate under low-noise conditions, but converges much more slowly in the early stage. The fixed higher exploration rate performs relatively poorly overall and has particular difficulty forming a stable policy in high-noise environments. These experiments show that exploration strategies should not be evaluated only by final success rate; environmental randomness, learning speed, and stability across random seeds should also be considered.
Show more
Read Article PDF
Cite